Hugging Face Integration Services
Hugging Face integrated for open-source models, custom training, and Inference Endpoints in 10 days.
Hugging Face is the GitHub of AI — 1M+ open-source models, Datasets, Spaces, and Inference Endpoints. We integrate Hugging Face for businesses needing open-source models (Llama 3, Mistral, BERT variants, Stable Diffusion fine-tunes), custom model training, or self-hosted inference via Inference Endpoints. Especially valuable for AI-mature teams wanting full model control beyond OpenAI/Claude.
Why Teams Choose Us for Hugging Face Integration
Specifics that matter when you are betting your business on a Hugging Face integration.
Hugging Face specialists — model selection across 1M+ options
Most teams stick to top-10 popular models. We help you find the right specialized model for your use case from Hugging Face's 1M+ — domain-specific BERTs (FinBERT, BioBERT, LegalBERT), language-specific (Indic, Arabic), task-specific (NER, QA, summarization).
Inference Endpoints for managed self-hosted
Hugging Face Inference Endpoints give you self-hosted-like control (your model, your GPU) with managed-service convenience. We deploy + autoscale + monitor without you managing GPUs directly.
Custom model fine-tuning + deployment
For domain-specific tasks (legal contract analysis, medical NER, customer support intent classification), fine-tuning a base model on your data outperforms generic LLMs. We handle the full pipeline: dataset prep → training → evaluation → deployment.
Sentence Transformers for embeddings (cheap RAG alt)
For cost-conscious RAG, open-source Sentence Transformers (BGE, E5, Mistral Embed) self-hosted on Hugging Face cost 1/10th of OpenAI embeddings at scale. We deploy + integrate into RAG stacks.
Everything You Get in a Hugging Face Integration
No fine print, no surprise add-ons. Every line below is included in our scope.
How We Ship Your Hugging Face Integration
Day-by-day, with milestones you can hold us to.
Use case audit + model selection
Match use case to right model from Hugging Face Hub.
Backend integration via Transformers / Inference Endpoints
Server-side Python integration or hosted Inference Endpoints.
Custom fine-tuning (if applicable)
Dataset prep, training run, evaluation, deployment.
Observability + cost optimization
Langfuse / W&B for monitoring; batch + caching.
Production go-live
Switch to live; 60-day support starts.
Hugging Face Integration Pricing
Fixed-price tiers in USD (global pricing). Equivalents in other currencies shown for reference. No hourly billing surprises.
Starter
For small teams shipping fast
₹70K for India · AED 5,500 for UAE
7–10 days- HF Inference API integration
- Single model (off-the-shelf)
- Basic observability
- 30 days support
Pro
For growing businesses needing the full feature set
₹1.8L for India · AED 13,000 for UAE
12–16 days- Inference Endpoints deployment + autoscaling
- Self-hosted Sentence Transformers for embeddings
- Multi-model routing
- Cost optimization
- 60 days support
Enterprise
For complex flows, marketplaces, and scale
Priced per scope
21+ days- Custom fine-tuning end-to-end
- AWS Bedrock / SageMaker deployment
- Multi-tenant model serving
- Dedicated SLA
- Quarterly performance review
We Integrate Hugging Face Across Every Major Stack
Your tech stack does not change our pricing. Pick yours below to see relevant work.
Trusted by Hugging Face Users in These Industries
Industry-specific patterns, compliance, and proven flows.
Real Hugging Face Integrations We Shipped
Specific outcomes, not vague testimonials.
Legal AI — Fine-tuned LegalBERT for contract clauses
Fine-tuned LegalBERT on 50K labeled contract clauses for legal SaaS. F1 score 0.91 on clause classification (vs 0.74 for GPT-4 zero-shot). Per-doc cost: $0.18 → $0.012.
15x cheaper at higher accuracy
Cost optimization — Migrate embeddings from OpenAI to BGE
Migrated SaaS embedding workload from OpenAI ($14K/month) to self-hosted BGE-large on HF Inference Endpoints ($1.4K/month). Quality matched on internal eval set.
$12.6K/mo saved
Healthcare — Custom medical NER on BioBERT
Trained BioBERT-based NER for medical entities (drugs, conditions, dosages) for clinical SaaS. Per-document NER 4x faster than GPT-4 + better recall.
4x speed, +12% recall
Why Codingclave for Hugging Face Integration
A side-by-side comparison vs hiring a freelancer or another agency.
| Feature | Codingclave (Us) | Freelancer | Other Agency |
|---|---|---|---|
| Model selection across 1M+ HF models | Curated for use case | Top-10 only | Default popular |
| Custom fine-tuning expertise | 12+ models trained | Almost never | Special service |
| OSS embeddings cost optimization | 70-95% savings | Default OpenAI | Default OpenAI |
| Time to launch | 10 working days | 21-45 days | 30-60 days |
| Pricing transparency | Fixed price | Hourly | Inflated |
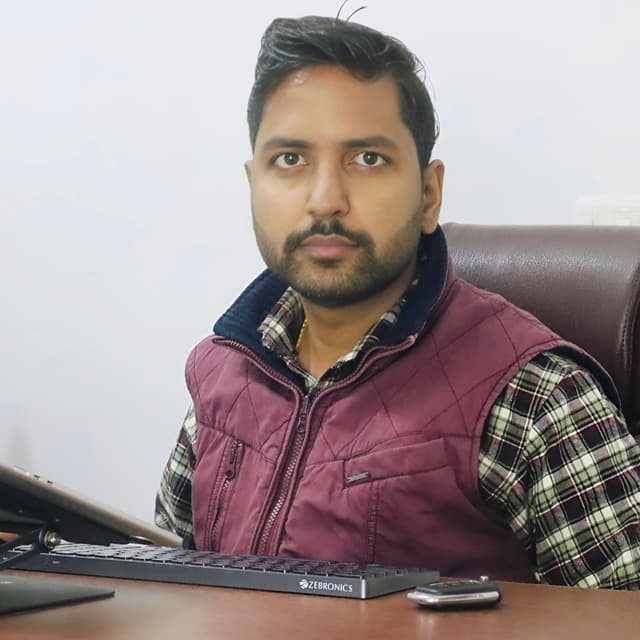
Talk Directly to Ashish for Your Hugging Face Integration
I personally review every Hugging Face integration we ship — scope, pricing, and delivery timeline. With 200+ projects shipped since 2017, a 100% Job Success Score on Upwork, and 4.9★ on Google, my reputation is on every integration we deliver. If something breaks at 2 AM, I am the one fixing it.
Lucknow, India · Available for calls in IST, GST, BST, EST · Free consultation
Hugging Face Integration — Common Questions
Everything teams ask before signing on.
Starts at $1,499 for HF Inference API + single off-the-shelf model. Pro at $3,699-$7,299 adds Inference Endpoints, self-hosted embeddings, multi-model routing, cost optimization. Enterprise (custom fine-tuning, AWS/Azure deployment) is custom — typically $9,000-$30,000.
Pick HF if: (1) you need a specialized model (legal, medical, multi-lingual that OpenAI doesn't do well), (2) you want OSS for full control + cost at scale, (3) you need custom fine-tuning. Pick OpenAI if: simplest path, no team to manage models, willing to pay premium.
Basic API: 7-10 days. Pro Inference Endpoints + multi-model: 12-16 days. Custom fine-tuning + production deployment: 21-60 days.
Often yes — for specialized tasks. Examples: LegalBERT fine-tuned on contracts beats GPT-4 zero-shot on clause classification (F1 0.91 vs 0.74). BioBERT fine-tuned on medical NER beats GPT-4 on entity extraction. Trade-off: requires labeled training data + ML expertise (we provide).
Self-host (via Sentence Transformers / BGE / E5) if you do >$1K/month on OpenAI embeddings — typical 70-95% savings at scale. Stick with OpenAI if <$1K/month (not worth ops overhead).
Managed model hosting on Hugging Face — you pick a model, HF deploys on dedicated GPU with autoscaling. Like AWS SageMaker but simpler. We use this for clients who want self-hosted-like control without GPU ops.
Pay-as-you-go at $90/hr or AI SLA at $500/month with 4-hour response. ~70% of clients move to SLA.
Related Integrations
Often paired with this one.
Ready to Build Something Great?
Talk to Ashish Sharma. Share your Hugging Face integration scope, get a fixed-price quote in 24 hours.
Reply Within 2 Hours
We respond fast. No waiting days for a callback or email. Get answers quickly.
100% Free Consultation
Tell us your idea. We'll give you an honest estimate, tech recommendations, and a roadmap — free.
200+ Projects Shipped
From government websites to SaaS products — we've delivered at every scale since 2017.
Upwork JSS
Projects